RDF

Building Shared Meaning - Get the Skills

Connect your people, your systems, your numbers and your AI

Every organisation I work with has the same problem wearing different clothes. The business means one thing, the systems mean another, the dashboards a third, and now the AI is confidently improvising a fourth. Shared meaning is the fix, and it is a learnable skill. Our course, Building Shared Meaning, runs in four weeks.

Training starts in just under four weeks, and deep discounts are available for early bookings. Details at the end of this article.

In earlier newsletters I set out what it takes to build shared meaning, and what it takes to turn that foundation into an ontology that AI agents can rely on. Several readers asked the obvious question: where do I, or my team, learn to do this? Building Shared Meaning is the first of our two courses and the one most people start with. It is five days, hands-on, and built for people who work between the business and solutions rather than deep in the technology.

Rather than walk through the timetable, let me show you where the skill pays off. There are five places, and you probably recognise all of them.

1. People and group communication

Most project failures are not technical. A business owner says "customer", an analyst hears one thing, a designer models another, the implementer builds a third, and the vendor's product assumes a fourth. Everyone is competent, everyone is using the same word, and nobody is talking about the same thing.

The course gives that conversation a discipline. You learn to:

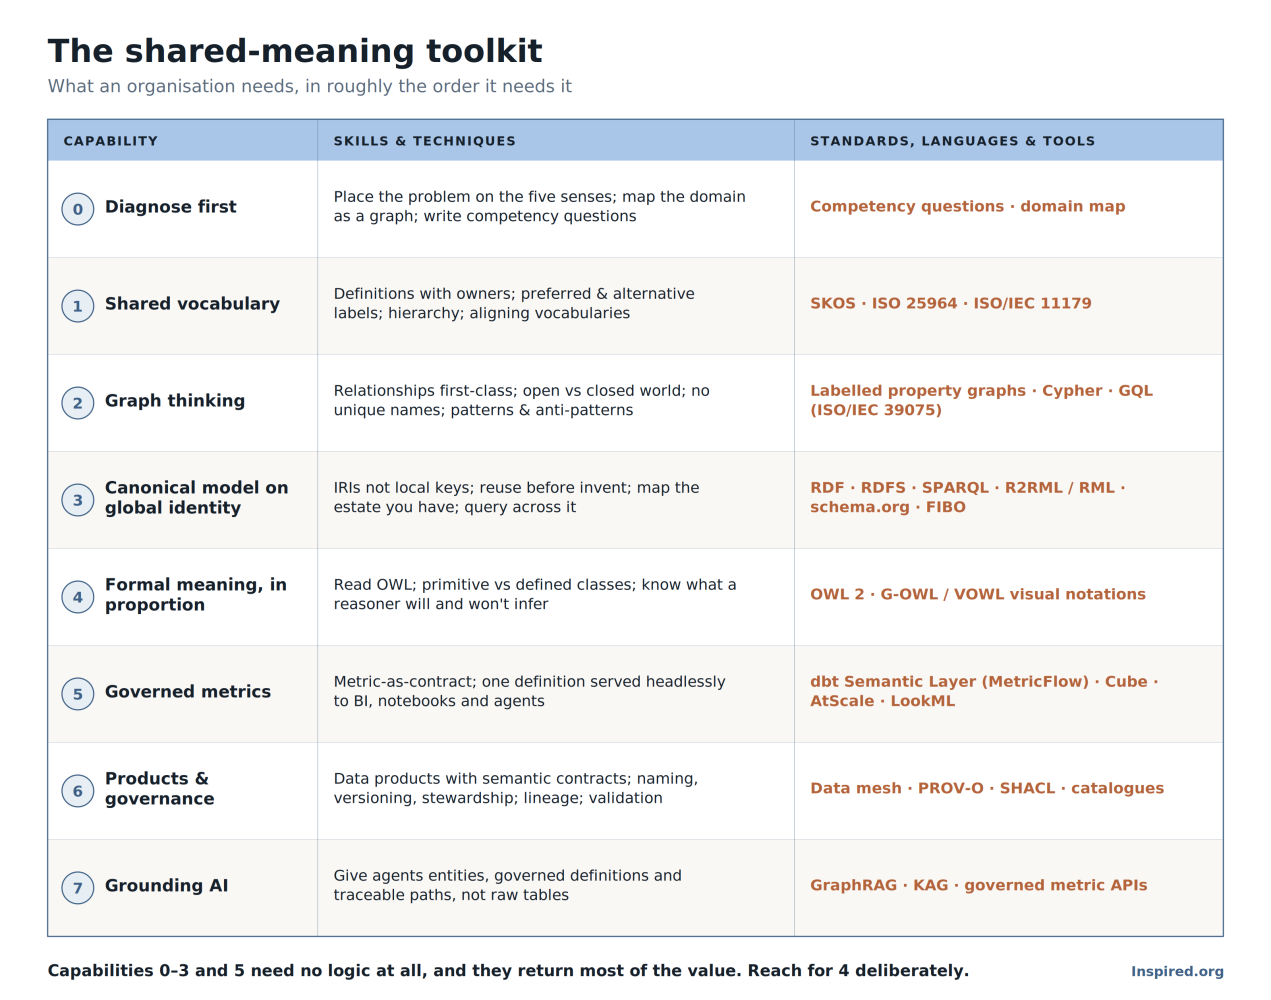
  • Start from the questions the business needs answered (competency questions), so the model is scoped by purpose rather than by argument

  • Elicit, agree and record meaning in workshops with domain experts, in a form the business can read and the technologists can build from

  • Build a governed vocabulary using SKOS, the Simple Knowledge Organization System: preferred terms, synonyms, broader and narrower concepts, agreed definitions

  • Hold the line with vendors. When you can state precisely what your terms mean, you can test a vendor's model against yours, instead of adopting theirs by default

This is the part people undervalue until they have done it. A shared vocabulary does more for a programme than another round of requirements documents. It essentially provides the nouns for all the requirements and specifications that follow.

2. Communication across business silos

Finance, sales, operations, risk and compliance each have good reasons for their own definitions. The trouble starts when the numbers have to meet: "active customer", "revenue", "incident", "product".

Participants learn to map those differences rather than argue them away. You identify where concepts genuinely coincide, where they overlap, and where they only share a name. You then record the result as a model each silo can recognise itself in. Two techniques do the heavy lifting: conceptual modelling that stakeholders can read, and a canonical model with global identity, so that "the same thing" is the same thing wherever it appears.

It builds on the tools you already know. Entity-relationship modelling, UML, Relational Schemas and the patterns literature all come with us. We change the assumptions underneath them so the model can span silos instead of describing one.

3. Integration across applications

Legacy systems, in-house applications, web services, and packaged ERP each carry their own schema and  idea of what a record means. Point-to-point integration multiplies the translation problem with every connection you add.

A shared model changes the economics. Each system maps once to the common meaning, instead of to every other system. On the course you work through:

  • How tabular and services data becomes a graph, including the mapping languages R2RML and RML and the thinking about identifiers and entity resolution behind them

  • RDF (Resource Description Framework) and property graphs side by side, and how to choose between them. How to work with them using the query languages SPARQL and Cypher, and the new ISO standard GQL

  • Reuse of existing standards, such as schema.org, Financial Industry Business Ontology (FIBO), gist Enterprise Ontology (Semantic Arts) and QUDT (Quantities, Units, Dimensions, Data Types), before you build anything yourself

You do not need to replace anything. The point is a layer of meaning that your existing estate can be mapped to.

4. Reliable business intelligence in real time, and support for compliance

This is the part of the course where analysts and BI practitioners get real value, and it is a deep session rather than an overview. The semantic layer is where governed metrics live: each measure defined once, tied to the model, and served consistently to every dashboard, report, query and application. When a metric is defined in one governed place, the argument about whose number is right stops being a weekly event.

You learn to define a governed metric, connect it to your BI tooling (the dbt Semantic Layer and Cube are the examples we use), and manage metric drift as the business changes. The same discipline serves real-time use: once the meaning is separated from the plumbing, a live feed and a monthly extract answer to the same definitions.

For regulated industries there is a second benefit. Banking, insurance, healthcare and pharmaceuticals are asked to show where a number came from, what it means and who owns it. Clear definitions, ownership, versioning and lineage are the raw material of that evidence, whether the driver is BCBS 239 on risk data aggregation, privacy law such as POPIA or the GDPR, or an auditor's questions. The course covers governance basics (naming, versioning, ownership), lineage and data products, and introduces SHACL, the Shapes Constraint Language, for validating data against agreed rules. A shared model does not make you compliant by itself, but it is hard to achieve compliance without one.
5. AI and agentic deployment at scale, with reliability

Large language models are fluent and, used alone, unreliable about your business. Retrieval over flat documents finds text that looks relevant. It cannot tell the model what your terms mean or how your entities relate. Ground the model in a governed graph and the picture changes: answers can be traced, terms are unambiguous, and an agent acts on definitions rather than guesses.

Course 1 gives you the foundation: why agents fail on flat data, how GraphRAG differs from vector retrieval in plain terms, and what a good ontology adds. It is an awareness-level introduction, deliberately. Building and proving the production ontology, enforcing rules and engineering the agent are the subject of Course 2, Engineering Reliable Agentic Automation. What Course 1 gives you is the thing Course 2 cannot do without: a domain you have scoped, a vocabulary you have governed and a model other people can trust.

One honest note. Most enterprises need a lot of vocabulary, canonical modelling and governed metrics, and only a small, careful amount of formal ontology. We teach it that way. The course also treats LLM-drafted ontologies for what they are: useful as an assistant, dangerous as an unreviewed author.

What you will leave with

Five days, about 36 contact hours, interactive throughout. No logic or programming background is needed, only comfort with data and business analysis. Over the week you move from why semantics matter and how graphs represent knowledge, through eliciting meaning and building a vocabulary, to reading ontologies, writing basic SPARQL, defining governed metrics and seeing how AI uses all of it.

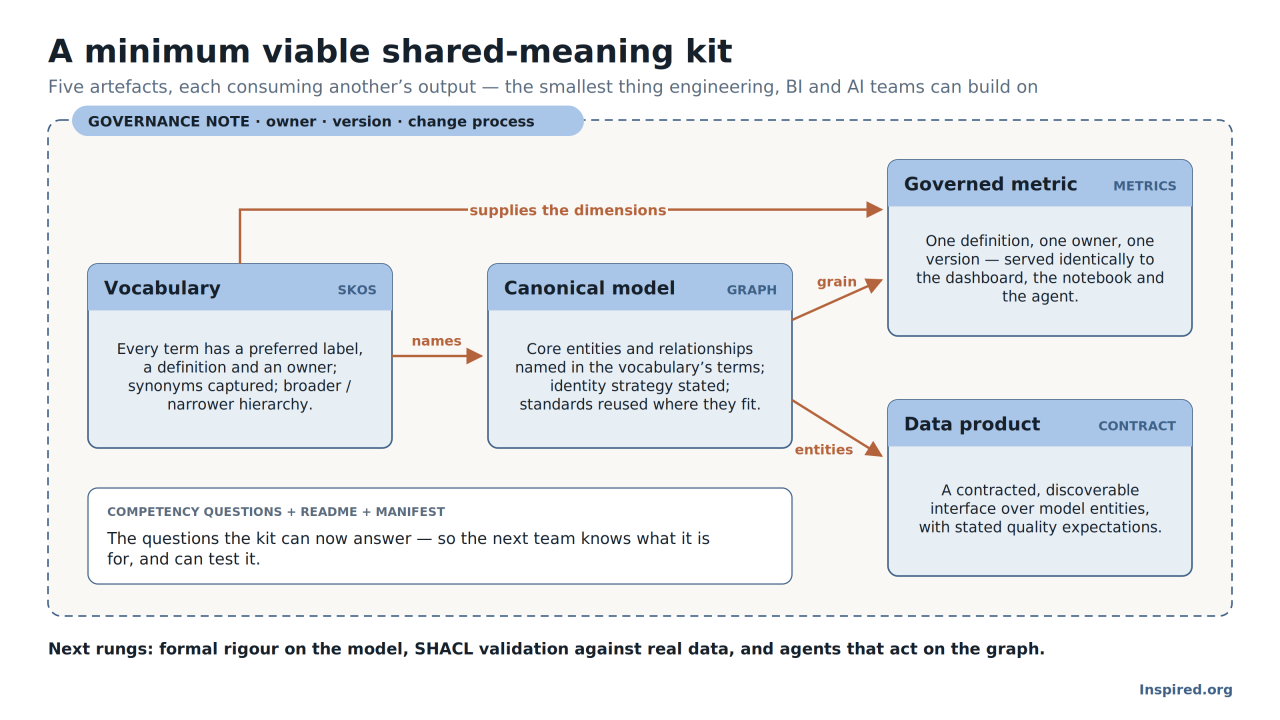
You finish with your own semantic starter pack for a domain you care about: competency questions, a conceptual model, a governed SKOS vocabulary, a governed metric tied to the model, and a clean hand-off to the specialists who take it further. You also leave able to do what most organisations are short of: act as the semantic translator between the business and the technical teams.

The course is suitable for business and systems analysts, BI and data practitioners, architects, designers, domain experts, and anyone on the vendor or implementation side who has to make several parties mean the same thing.

Booking

The course starts in just under four weeks.

Deep discounts are available for early bookings, so if you are keen to join us, now is the time to act. Places are limited to keep the work hands-on.

Full details (coverage, timing, format, pricing, booking) here: https://www.inspired.org/course-1-build-shared-meaning

To ask whether it fits your team, or about special arrangements, contact us through inspired.org or message me directly. If several people in your organisation would benefit, we can talk about group arrangements.

References and standards

  1. W3C, SKOS Simple Knowledge Organization System Reference, Recommendation, 2009 — https://www.w3.org/TR/skos-reference/

  2. W3C, R2RML: RDB to RDF Mapping Language, Recommendation, 2012 — https://www.w3.org/TR/r2rml/

  3. W3C, SPARQL 1.1 Query Language, Recommendation, 2013 — https://www.w3.org/TR/sparql11-query/. ISO/IEC 39075:2024, GQL.

  4. W3C, Shapes Constraint Language (SHACL), Recommendation, 2017 — https://www.w3.org/TR/shacl/

  5. Basel Committee on Banking Supervision (2013), Principles for effective risk data aggregation and risk reporting (BCBS 239) — https://www.bis.org/publ/bcbs239.htm

  6. Edge, D. et al. (2024), "From Local to Global: A Graph RAG Approach to Query-Focused Summarization" — arXiv:2404.16130.

  7. Allemang, D., Hendler, J. & Gandon, F. (2020), Semantic Web for the Working Ontologist, 3rd edition, ACM Books.
Your data has structure. It doesn't have meaning

Why enterprise AI has made a thirty-year-old question urgent — and what the move from Information Engineering, UML and relational modelling to graph, semantic and ontology-driven execution actually demands of practitioners.

The problem is not the model. It's the ground truth.

Shared meaning is not a new problem. Warehouse teams have been fighting "whose definition of revenue?" for thirty years. What changed is who is now reading the data.

A traditional report was read by an analyst who knew that "active customers" in the marketing dashboard was not the "active" the risk team used. She carried the caveat in her head, applied it, and moved on. The ambiguity was real but bounded — it lived in a few expert skulls and travelled no further than a meeting.

Put an agent in that seat. Ask it "how many active customers do we have in the North region, and what is their total exposure?" It will join the marketing table's active flag to the risk system's exposure column, sum the result, and return a confident number in fluent prose. It does not know the two systems mean different things by customer. It has no caveat. And its output looks exactly as authoritative as a correct answer would.

Three properties of AI-mediated work turn latent ambiguity into active cost:

  • Amplification. A human analyst makes one join an hour. An agent makes thousands, unsupervised. Every wrong assumption about what a field means is now executed at machine scale

  • Composition. Agents chain steps. A subtly wrong definition at step one propagates, and by step five the provenance of the error is gone. The answer is wrong and unexplainable at once

  • Opacity of confidence. The failure mode is not a crash or a NULL. It is a plausible, wrong, actionable answer - the expensive kind

The instinct, when the agent gets it wrong, is to reach for a bigger model or better prompts. But the error is not in the model's reasoning. It is in the ground truth the model reasoned over. If customer denotes four different things in four systems, no amount of model capability recovers the one you meant — because that thing was never written down anywhere a machine could read it.

Semantics is the missing input, not a missing capability.

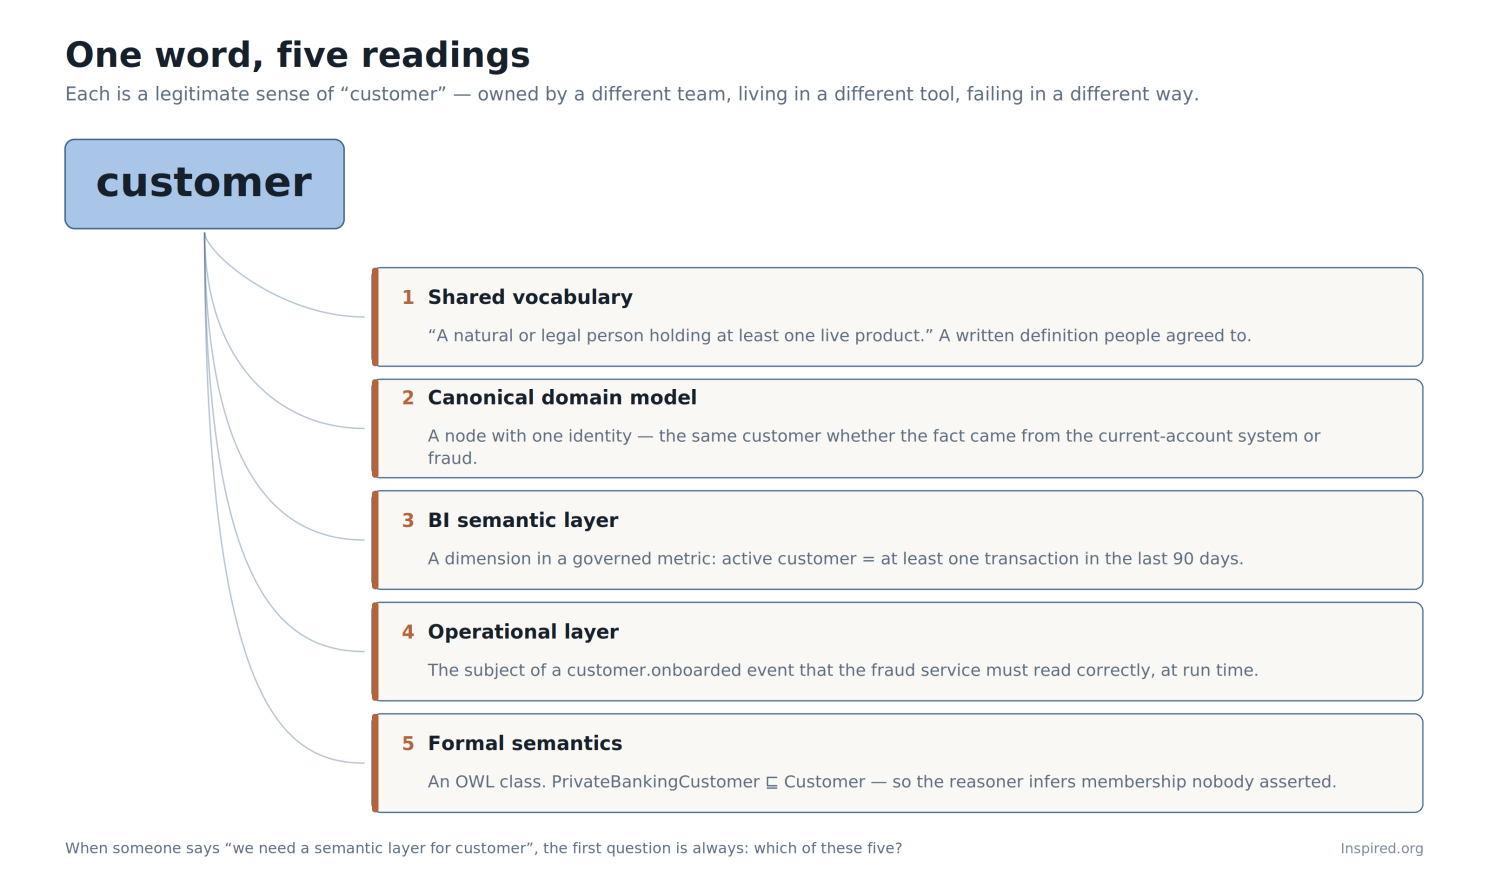
"Semantic" means five different things

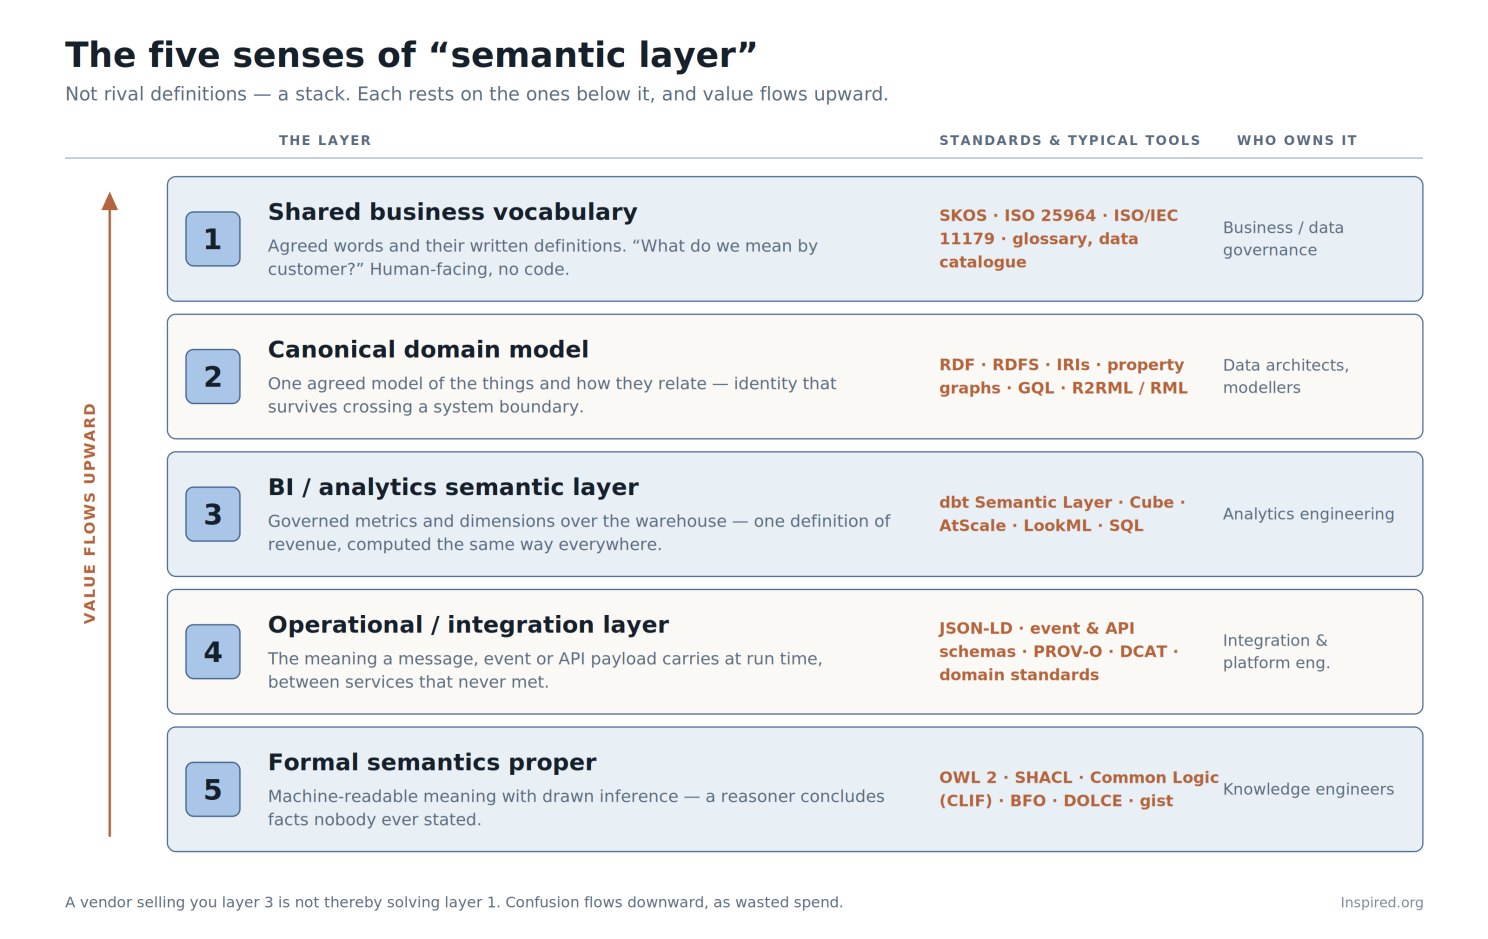
Here is where most programmes go wrong before they start. "Semantic layer" is the most overloaded phrase in enterprise data. Serious people use it to mean at least five distinct things that live in different places, are owned by different people, cost different amounts and solve different problems.

They are not rival definitions. They are a stack:

Read one word — customer — down that stack and the point becomes clear. Each reading is legitimate. Each is owned by a different team. Each fails in a different way.

Why this matters commercially: a retail bank funds a "Single View of Customer" programme. The deck talks about AI. The budget goes on a layer-3 analytics semantic layer, because that is what the vendor demonstrated. Eighteen months later the executive dashboard still shows three different customer counts — because the actual problem was layer 2. The same person exists as four unreconciled records in four systems, and no metrics layer reconciles identities it was never given. The programme built a precise calculator on top of an unresolved question.

Buying layer 3 to fix a layer-1 or layer-2 problem is the single most expensive mistake in this field.

Four demands, and the standards that answer them

1. Shared meaning — a common controlled vocabulary

Before anything else: do people agree what the words denote? "A customer is a natural or legal person who holds at least one live product with the bank." Plain language, agreed by humans, no code.

Most "data quality" disputes are vocabulary disputes wearing a technical costume. The formalisation is cheap and unglamorous: SKOS — the Simple Knowledge Organization System (W3C Recommendation, 2009) gives you concepts, preferred and alternative labels, broader/narrower hierarchies and mappings between schemes. ISO 25964 covers thesaurus construction and interoperability; ISO/IEC 11179 covers metadata registries and the discipline of naming and defining a data element properly.

This is the twenty per cent of the stack that needs no logic at all and returns most of the value. Skip it and everything above inherits the ambiguity.

2. Agreed derivation — the semantic layer for BI

Everyone agrees what a customer is, and two dashboards still disagree on the count, because the calculation lives in two places. The answer is a governed metric definition — active customer = at least one transaction in the last 90 days — written once, over the warehouse, and resolved identically by the dashboard, the notebook and the agent.

This is the sense most vendors mean today: the dbt Semantic Layer, Cube, AtScale, LookML. It is genuinely valuable, and it is also where the confusion concentrates, because it is the layer with the biggest marketing budget. A metrics layer computes flawlessly over whichever records you feed it. If those are four unreconciled customers, the metric is precise and wrong.

The real prize here is not the dashboard. It is that an agent can call a governed metric instead of misjoining raw tables.

3. Integration and interoperability — semantic expression

Point-to-point mapping does not survive past a handful of systems: n systems need n(n−1)/2 mappings, each with its own quiet assumptions. Meaning that travels needs to be expressed in a form that is not owned by any one system.

  • Semantic data is best expressed in graphs. A graph is a connected set of statements, conceptually nodes and edges. e.g. John -worksFor-> Enron -sells-> Oil

  • Graphs can be stored in simple fact statements (see RDF) or Labelled Property Graphs (see LPG)

  • RDF — the Resource Description Framework (W3C; RDF 1.1 in 2014, with RDF 1.2 reaching Candidate Recommendation in April 2026) reduces everything to the triple: subject, predicate, object. e.g. John worksFor Enron; Enron sells Oil. RDFS — RDF Schema adds classes, properties and subsumption (class subtyping)

  • IRIs — Internationalized Resource Identifiers replace local primary keys with globally resolvable names, so "the same customer" is a claim two systems can actually make

  • SPARQL — the SPARQL Protocol and RDF Query Language (1.1, 2013; 1.2 in draft) provides queries and updates across a graph of triples

  • RDF vs LPG — RDF data stores (otherwise known as Triple Stores) can accommodate data without schema (or with) and can expand easily to accommodate new data without structure change. They are best for integrating data from heterogeneous sources. Labelled Property Graphs are more efficient and best for transactional and operational data

  • R2RML — the Relational DB to RDF Mapping Language (W3C, 2012) and RML — the RDF Mapping Language lift the relational and file-based estate you already have into RDF form, declaratively, without rewriting the sources

  • JSON-LD — JavaScript Object Notation for Linked Data (1.1, W3C, 2020) carries the same meaning inside ordinary API payloads, which is how layer 4 gets done in practice

  • On the property-graph side, GQL — the Graph Query Language (ISO/IEC 39075:2024) is now an ISO standard in its own right, and SQL/PGQ (part of ISO/IEC 9075:2023) brings graph pattern matching into SQL. The RDF-versus-LPG argument is largely over: mature programmes run both and bridge between them

  • Reuse beats invention: There are many sources of well defined models addressing generic requirements as well as specific disciplines. Consult schema.org, FIBO — the Financial Industry Business Ontology, SNOMED CT — Systematized Nomenclature of Medicine, Clinical Terms, QUDT — Quantities, Units, Dimensions and Data Types, PROV-O — the PROV Ontology for provenance, DCAT — the Data Catalog Vocabulary for datasets

Using these technologies allows merging and reaching consensus on definition and holding that stable and shared in a standard format.

4. Reliability and agentic automation — formal ontology backed by logic

Here the stakes change. If an agent acts on your model, "roughly right" stops being a documentation problem and becomes an operational risk. That demands semantics formal enough for a machine to check.

  • OWL 2 — the Web Ontology Language (W3C Recommendation, 2012) sits on description logics, a decidable fragment of first-order logic. Its profiles — EL, QL, RL and the full DL — are deliberate trade-offs between what you can say and what a reasoner can compute in reasonable time. Choosing the profile is an architectural decision, not a detail

  • SHACL — the Shapes Constraint Language (W3C Recommendation, 2017; 1.2 drafts in progress) does the job OWL was never designed for: validating that actual data conforms to a stated shape. OWL says what things are; SHACL says what a valid record looks like. Conflating them is the most common beginner error in the field

  • Common Logic (ISO/IEC 24707:2018), and its CLIF — Common Logic Interchange Format syntax, expresses the constraints description logic deliberately cannot: n-ary relations, multi-property rules, conditions over time. Paired with a theorem prover and a model finder, it also lets you verify an ontology — state the intended models, prove the entailments you expect, and check that your axioms are independent and consistent. This is the discipline that separates an engineered ontology from a plausible-looking one

  • Top-level ontologies give your concepts somewhere to stand: BFO — the Basic Formal Ontology (ISO/IEC 21838-2:2021), DOLCE — the Descriptive Ontology for Linguistic and Cognitive Engineering, and gist (Semantic Arts small business high level ontology). OntoClean (Guarino & Welty) supplies the analytical tests — identity, rigidity, unity, dependence — that catch the taxonomy errors everyone else ships

Only at this rung does an agent get something it can be held to: classifications it can derive, constraints it can be blocked by, and an audit trail explaining why it concluded what it concluded.

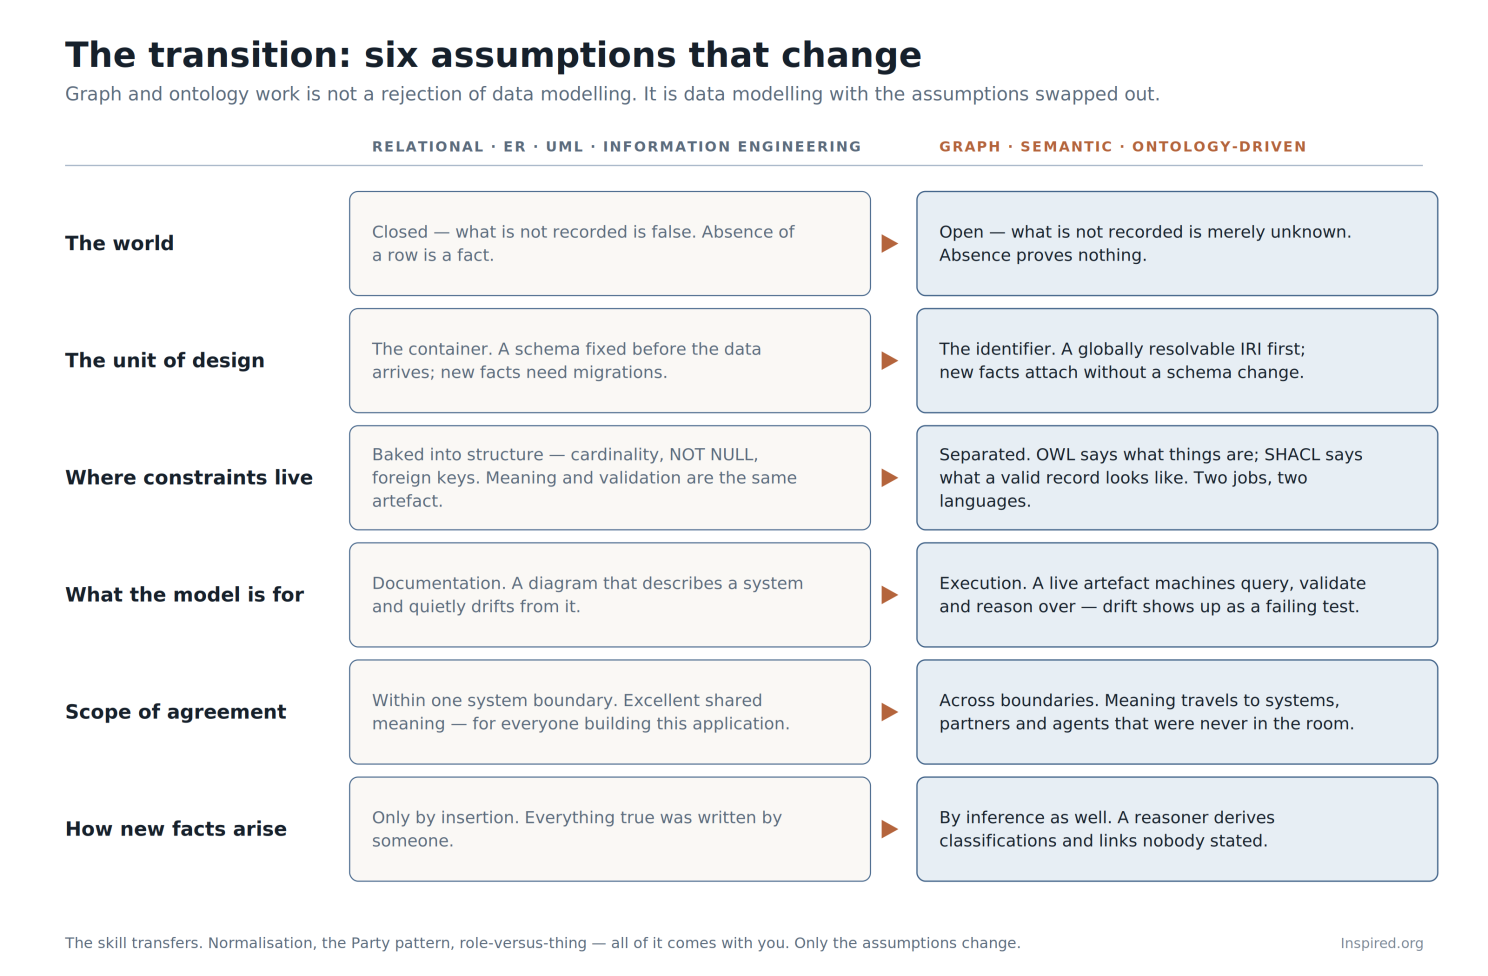
The transition practitioners actually have to make

To be fair to the tools we already use, they carried us a very long way and none of this asks you to throw them out.

Codd's relational model (1970) gave data a rigorous mathematical foundation and the normalisation theory that removes update anomalies — arguably the most successful idea in applied computing. Chen's entity-relationship modelling (1976) gave us the picture: entities, attributes, cardinalities, drawn so a business person can read it and a database can be generated from it. UML class diagrams and the wider Information Engineering tradition added object structure and the discipline of conceptual → logical → physical design. The patterns literature — Hay, Simsion & Witt — is full of hard-won wisdom that remains correct: the Party pattern, role versus thing, resolving many-to-many relationships properly.

All of it comes with you. Graph modelling is not a rejection of data modelling. It is data modelling with the assumptions resolved.

The hard part is not the standards. It is the unlearning — and in my experience excellent data modellers find this transition harder than beginners do, precisely because the old instincts are so good. Thirty years of closed-world reflexes ("if there's no row, it didn't happen") do not switch off because you read the OWL primer. Training has to be designed around that, not around the specification.

Where to start

Most enterprises need a great deal of layers 1 to 3 and a careful, small amount of layer 5. Formal ontology is the most powerful and the most over-applied technique on the map. Reaching for OWL when a governed glossary and a resolved identity would have done is how semantic programmes acquire their reputation for cost and delay.

There is a newer failure mode too. Large language models will happily draft you an ontology in minutes. Without competency questions, OntoClean analysis, SHACL validation and reasoner checks, what you get is a vibe ontology: fluent, plausible, and unverifiable — the same failure as the confident wrong answer, one level further up the stack. Assisted, then verified. In that order.

What we're doing about it

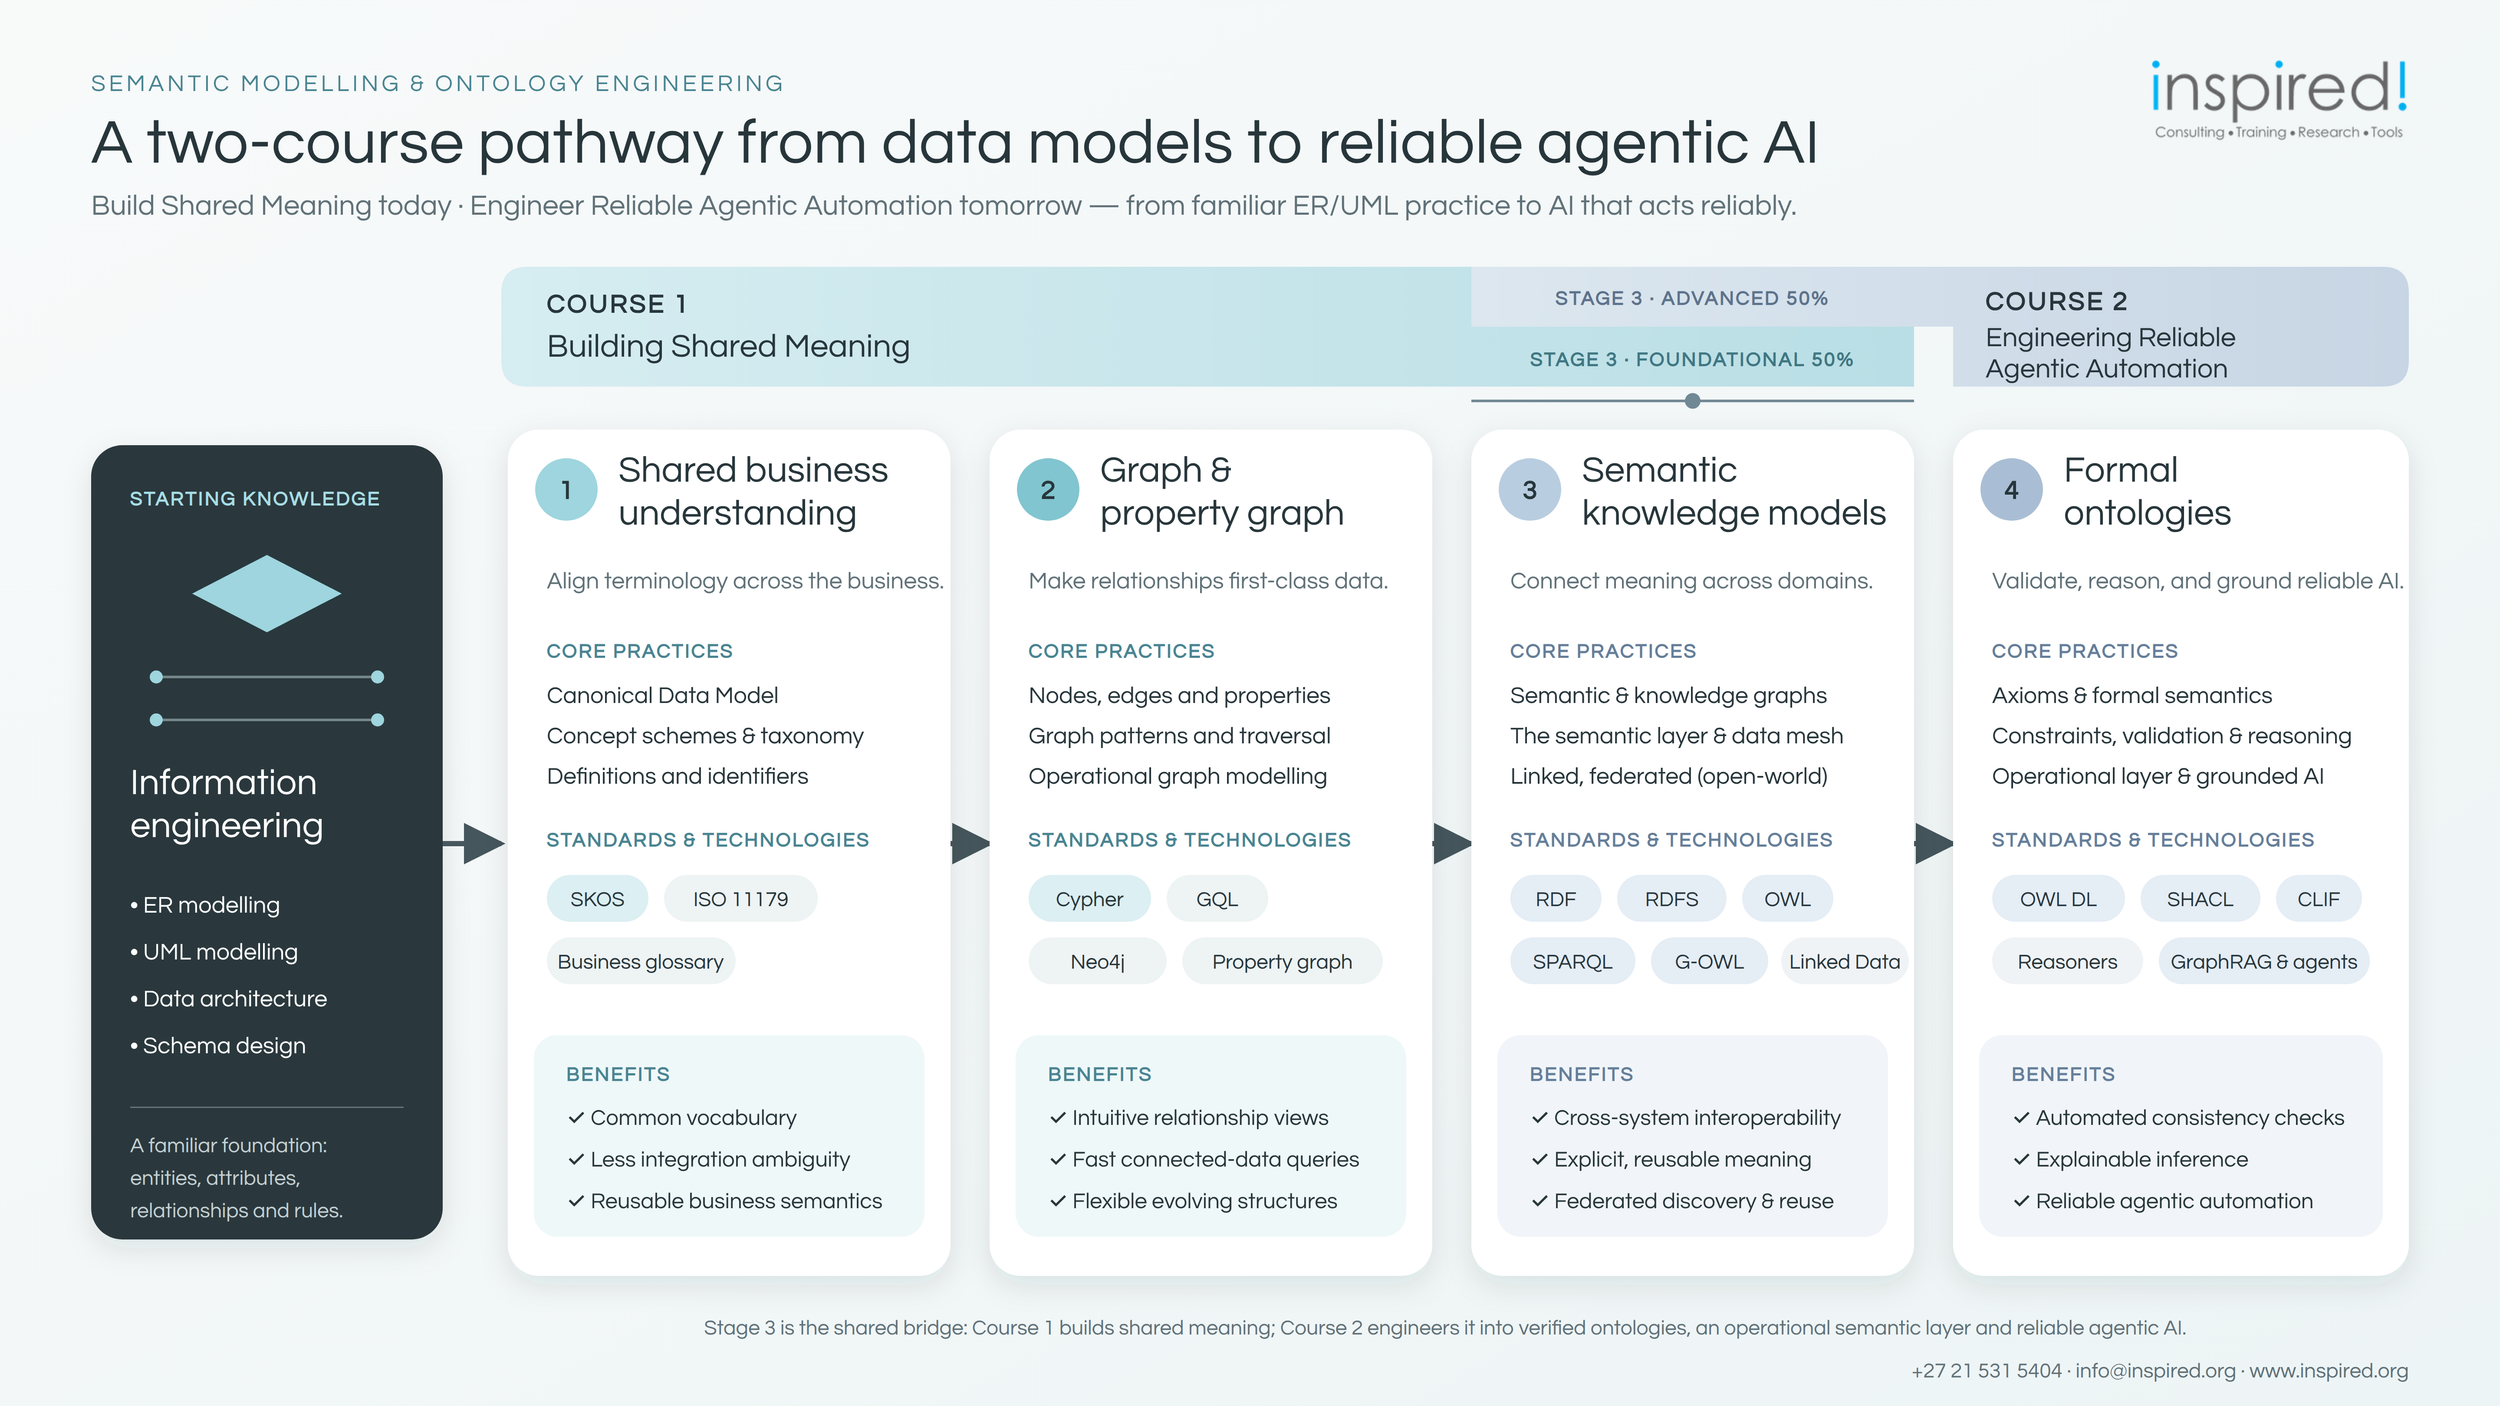
These threads — shared vocabulary, the canonical model, the semantic layer, integration, formal ontology, and the bridge into agentic AI — are what we have spent this year building a training path around.

We're introducing it as two courses: a transition course for commercial analysts, BI practitioners and domain experts who need to become the bridge to semantic work; and an advanced engineering course for modellers, ontologists and AI implementors who have to build the solution and put it into production.

Ready to make this shift on your own data estate?

Course 1: Building Shared Meaning starts 19–23 October.


References and standards

Standards

  1. W3C, RDF 1.1 Concepts and Abstract Syntax, Recommendation, 2014 — w3.org/TR/rdf11-concepts; RDF 1.2 Concepts and Abstract Data Model, Candidate Recommendation, 2026 — w3.org/TR/rdf12-concepts

  2. W3C, SKOS Simple Knowledge Organization System Reference, Recommendation, 2009 — w3.org/TR/skos-reference

  3. W3C, OWL 2 Web Ontology Language Primer, 2nd edition, 2012 — w3.org/TR/owl2-primer

  4. W3C, Shapes Constraint Language (SHACL), Recommendation, 2017 — w3.org/TR/shacl; SHACL 1.2 Core, Working Draft — w3.org/TR/shacl12-core

  5. W3C, SPARQL 1.1 Query Language, Recommendation, 2013 — w3.org/TR/sparql11-query

  6. W3C, R2RML: RDB to RDF Mapping Language, Recommendation, 2012 — w3.org/TR/r2rml

  7. W3C, JSON-LD 1.1, Recommendation, 2020 — w3.org/TR/json-ld11

  8. ISO/IEC 39075:2024, Information technology — Database languages — GQL

  9. ISO/IEC 24707:2018, Information technology — Common Logic (CL)

  10. ISO/IEC 21838-2:2021, Top-level ontologies — Basic Formal Ontology (BFO)

  11. ISO 25964, Thesauri and interoperability with other vocabularies; ISO/IEC 11179, Metadata registries

Literature

  1. Codd, E.F. (1970), "A Relational Model of Data for Large Shared Data Banks", Communications of the ACM 13(6).

  2. Chen, P. (1976), "The Entity-Relationship Model — Toward a Unified View of Data", ACM TODS 1(1).

  3. Berners-Lee, T., Hendler, J. & Lassila, O. (2001), "The Semantic Web", Scientific American.

  4. Guarino, N. & Welty, C. (2009), "An Overview of OntoClean", in Handbook on Ontologies, Springer.

  5. Allemang, D., Hendler, J. & Gandon, F. (2020), Semantic Web for the Working Ontologist, 3rd edition, ACM Books.
  6. Hogan, A. et al. (2021), "Knowledge Graphs", ACM Computing Surveys 54(4).

  7. Noy, N. et al. (2019), "Industry-scale Knowledge Graphs: Lessons and Challenges", Communications of the ACM 62(8).

  8. Suárez-Figueroa, M.C. et al. (2012), Ontology Engineering in a Networked World (the NeOn methodology), Springer.

  9. Grüninger, M. & Fox, M. (1995), "Methodology for the Design and Evaluation of Ontologies", IJCAI Workshop on Basic Ontological Issues in Knowledge Sharing.

  10. Lewis, P. et al. (2020), "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks", NeurIPS — arXiv:2005.11401

  11. Edge, D. et al. (2024), "From Local to Global: A Graph RAG Approach to Query-Focused Summarization" — arXiv:2404.16130

Graham McLeod · Inspired.org