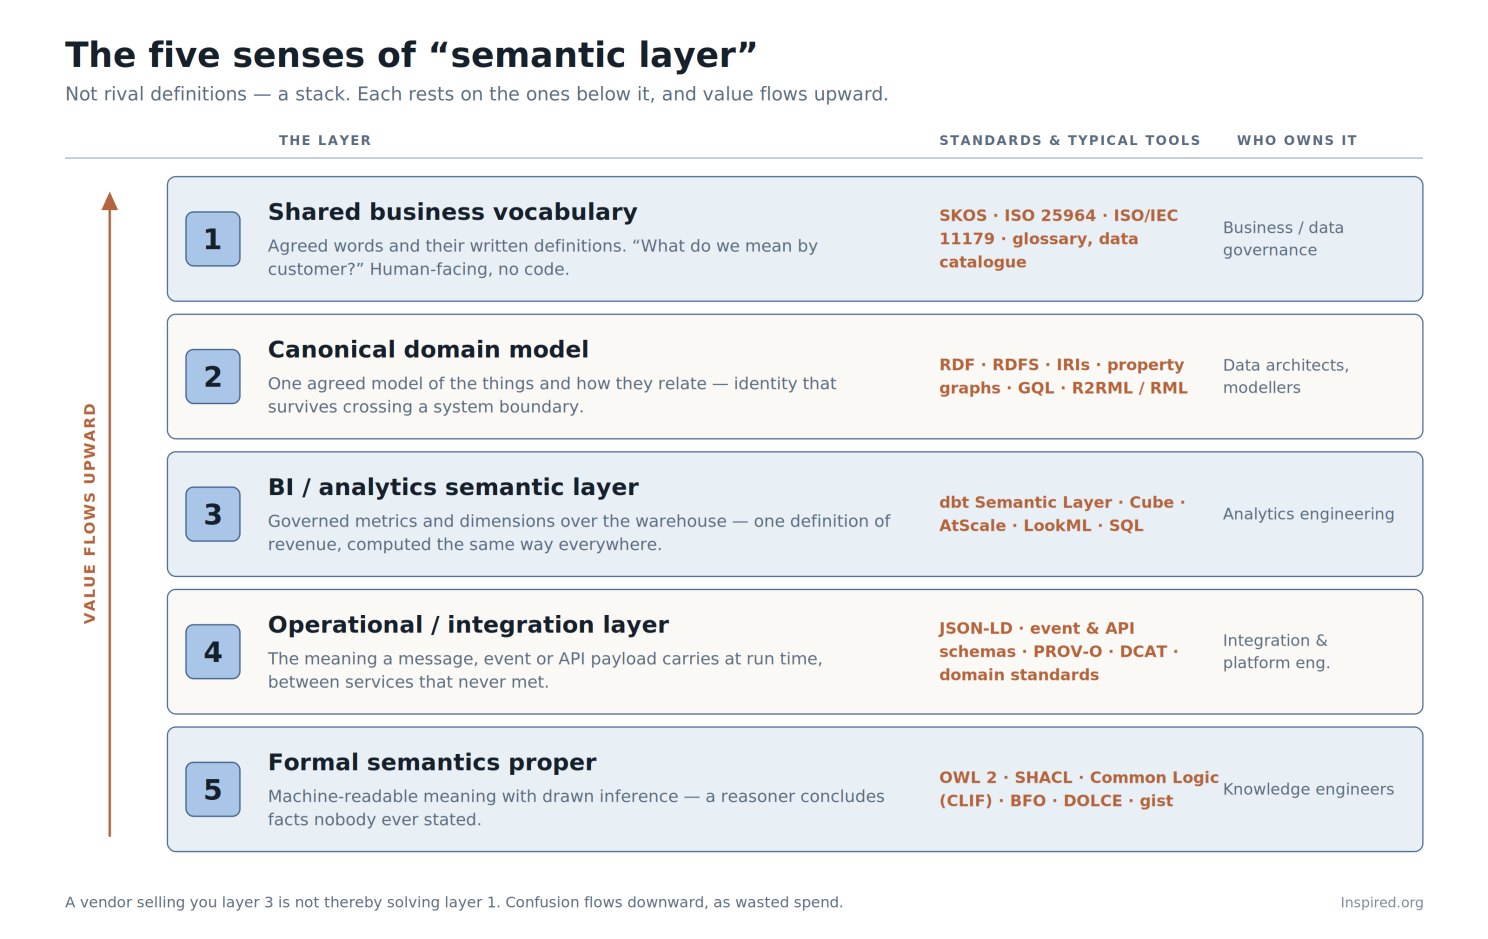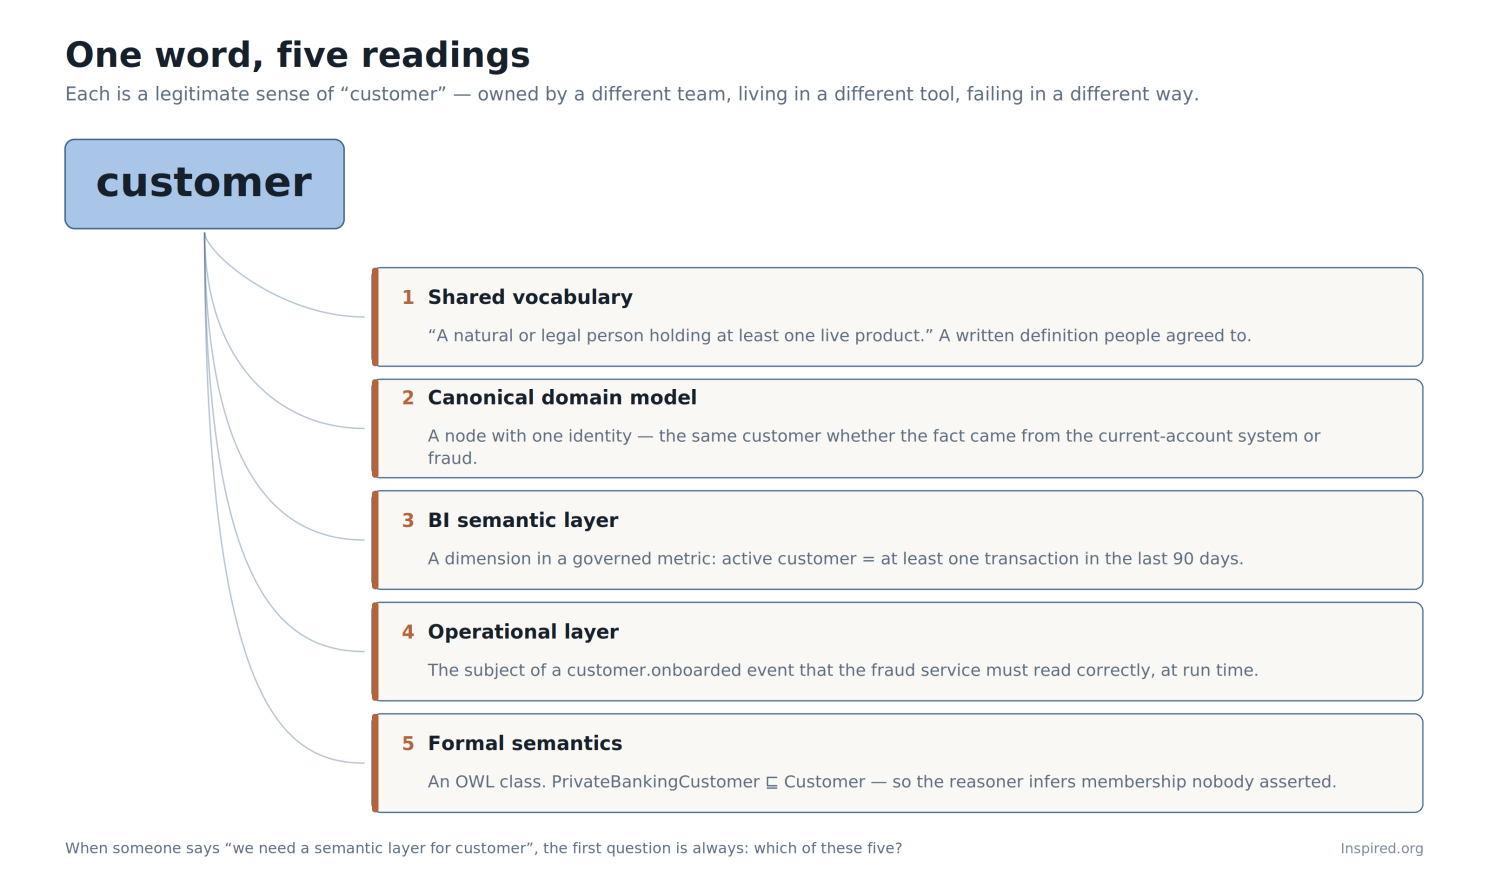
Last time I set out what it takes to build shared meaning: a governed vocabulary, a canonical model on global identity, governed metrics and data products. This piece picks up where that stopped. How do you turn that foundation into a formal ontology, prove it, and deploy it as production infrastructure that enforces your business rules, protects your data, and lets AI agents act without improvising?
Why agents raise the bar
A wrong number on a dashboard gets noticed by a person, usually before it does much harm. An agent that books, approves, reorders or escalates acts on what it believes, at machine speed, and nobody reads the reasoning first. The cost of an ambiguous definition, a duplicated customer or an unstated rule goes up sharply.
The foundation from last time answers "what do we mean?" Production agents also need four further answers:
Is the model right? Does it say what we intend, and nothing we do not?
Is it consistent, and can we show it? Not "it looked fine in review", but evidence
Are the rules enforced where it matters? At ingest, at write, at the moment an agent acts
Will it run at scale, securely? With the load, the access controls and the audit trail a production system needs
An LLM cannot supply these on its own, however fluent it is. They have to be engineered into the infrastructure the agent runs on, and the ontology is the place where they are written down once.
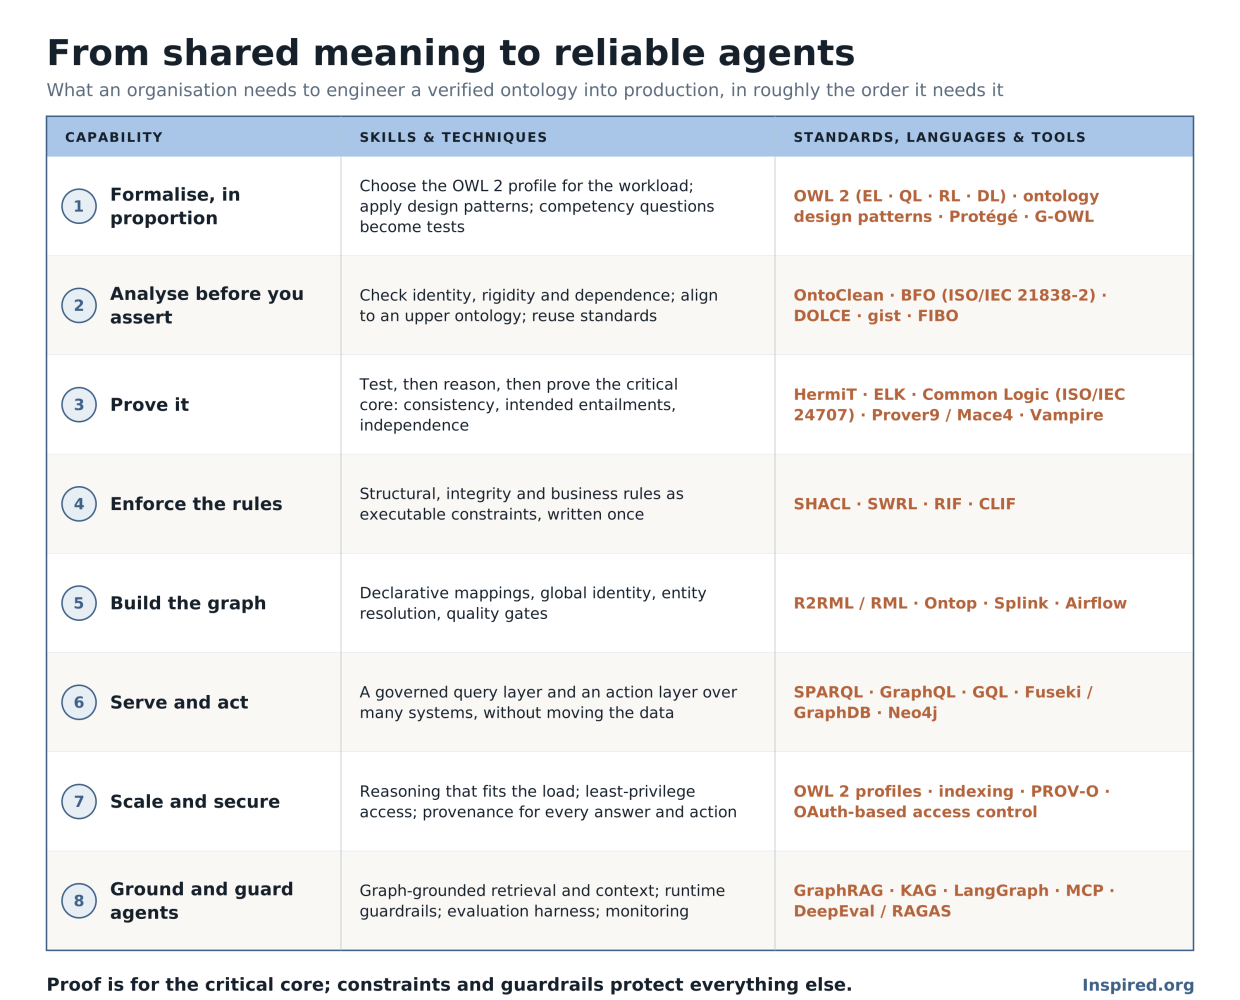
1. Formalise, in proportion
We do not start from a blank page. The SKOS vocabulary and canonical model from last time are the raw material, and the competency questions you wrote then become the specification: every question the ontology must answer is a test it must pass.
Formalising means moving from "these terms are related" to "this is what these terms necessarily mean", in OWL 2 — the Web Ontology Language. The skills go well beyond reading it:
Modelling with restrictions and property characteristics. Transitive, functional, inverse and disjoint constraints are the difference between a diagram and a model a machine can check
Choosing the profile deliberately. OWL 2 comes in profiles that trade expressivity for tractability. Existential Language (EL) and Rule Language (RL) reason in polynomial time and suit large data. Query Language (QL) is designed so that queries can be rewritten into SQL over the source databases. Full Description Logic (DL) is the most expressive and can be very expensive. This is a deployment decision as much as a modelling one, and it is the first one that determines whether the result will scale
Ontology design patterns and reuse. Content patterns, the eXtreme Design method and modularisation let you model faster and more soundly than inventing every structure afresh
Visual design for stakeholders. G-OWL, the complete visual syntax for OWL 2 that I mentioned last time, keeps the domain experts in the review loop, which is where most formal ontologies quietly lose them
The point I made from last time stands. Most of an enterprise value comes from the earlier layers, and a small, careful amount of formal ontology goes where it earns its keep: the core concepts that agents will reason over and act on.
2. Analyse before you assert
Formal languages let you say things that are wrong with great precision. The usual failures are not syntax errors. They are modelling errors: a role treated as a kind of thing, a part-whole relation mistaken for subclassing, a class that mixes things with different identity criteria.
OntoClean (Guarino & Welty) is the established method for catching these. You tag each class with four meta-properties (rigidity, identity, unity, dependence) and the rules show you where a taxonomy is unsound. E.g.: "Student" is a role a person plays, not a subclass of "Person", and a model that makes it one will misbehave the first time someone graduates.
Then anchor the model. A foundational (upper) ontology such as BFO — the Basic Formal Ontology (ISO/IEC 21838-2:2021), DOLCE or the business-oriented gist gives your concepts a consistent footing and makes your model easier to align with others. And reuse what already exists: FIBO in finance, SNOMED CT in health, QUDT for units. Reuse is cheaper than invention and makes you interoperable by default.
3. Prove it
"Prove" covers three levels of assurance, each stronger and narrower than the one before. A sensible programme uses all three, in proportion.
Test. Treat the ontology like software. Competency questions become executable tests that run on every change, and pitfall scanners such as OOPS! catch common design errors. This level is cheap and catches a great deal
Reason. A description-logic reasoner (HermiT for full OWL 2 DL, ELK for the EL profile) checks consistency and satisfiability, classifies the model, and, when something is wrong, produces justifications: the minimal set of axioms responsible. That turns "the reasoner says it is inconsistent" into a fixable defect
Prove. OWL cannot express everything an enterprise cares about: relationships between more than two things, rules that cut across properties, general constraints. For those you move to first-order logic and Common Logic (ISO/IEC 24707:2018), written in its CLIF — Common Logic Interchange Format dialect. A theorem prover (Prover9, Vampire) shows that an intended consequence really follows from your axioms. A model finder (Mace4) searches for a counter-example, and finding one shows the axioms permit something you did not intend. Together they let you check consistency, intended entailments and whether each axiom pulls its weight. Repositories such as COLORE hold verified ontologies you can learn from and reuse
Be realistic about the third level. First-order proof can be slow and is not guaranteed to terminate, and it takes specialist skill. Apply it to the small core where a flaw would be expensive: the definitions that gate payments, safety decisions or regulated outcomes. For everything else, testing, reasoning and runtime constraints give you strong assurance at a fraction of the cost.
4. Enforce the rules
This is where business rules, structural constraints and integrity constraints stop being documentation. The key point is that different rules live in different places, and mixing them up is a common source of surprises:
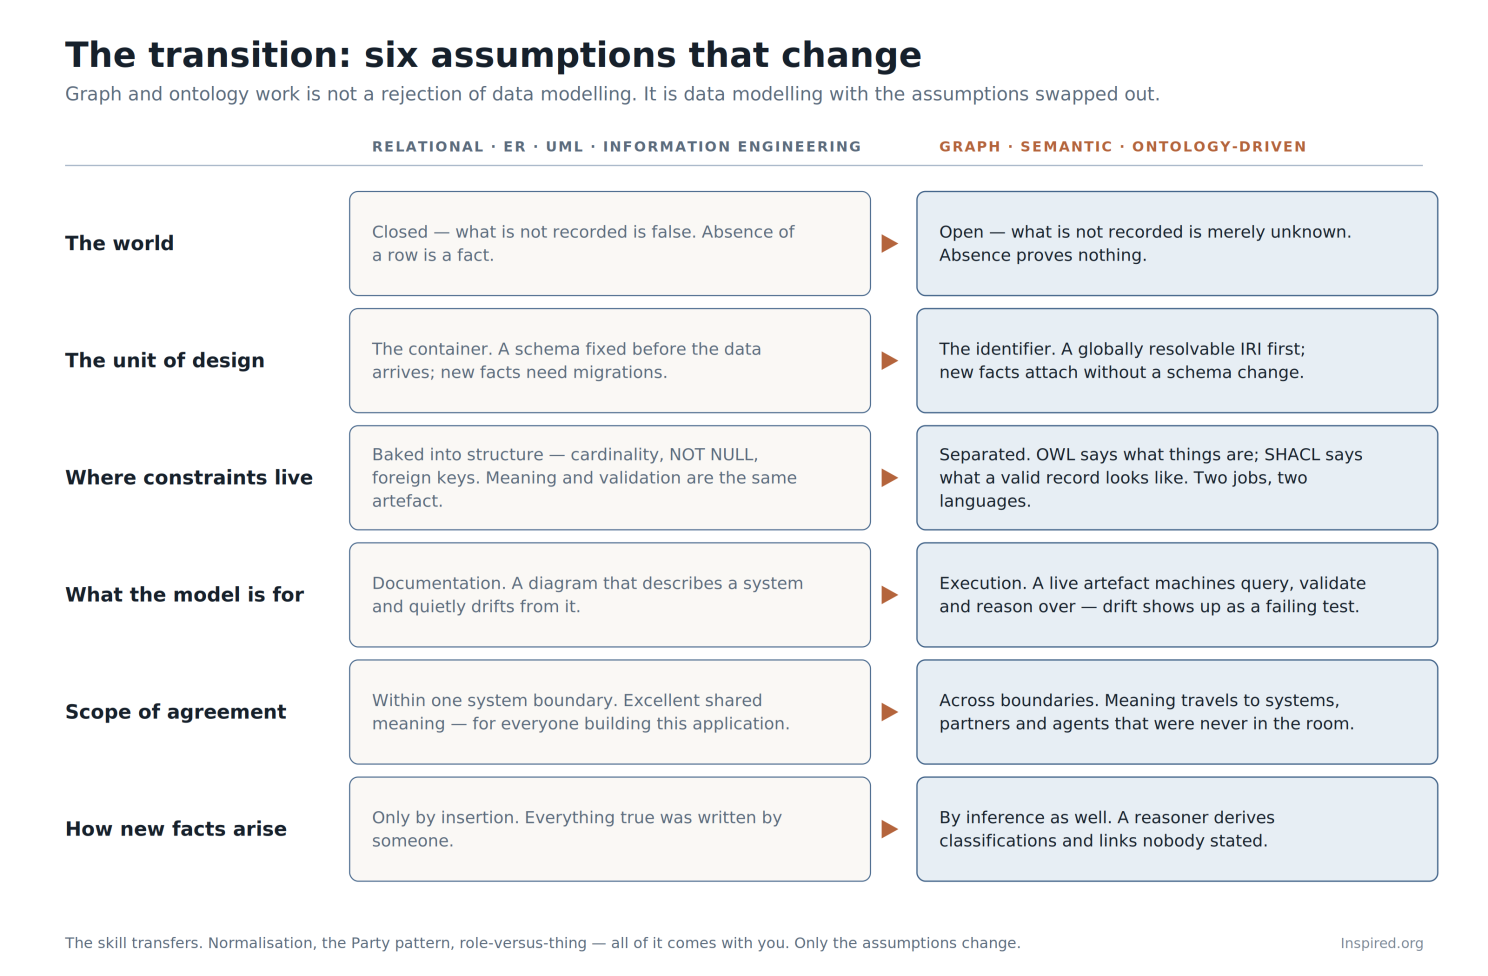
OWL says what things are, under the open-world assumption. A missing fact is unknown, not false, so OWL will not reject a record for being incomplete
SHACL — the Shapes Constraint Language says what a valid record or action looks like, checked closed-world against the data in front of it: required properties, cardinalities, datatypes, value ranges, allowed value sets, relationships that must exist. These are your structural and integrity constraints, and SHACL reports each violation in a standard, machine-readable form. SHACL 1.2 is still a Working Draft at the W3C, so check which engine supports what
Rules beyond OWL. Derivations and constraints that exceed description logic go in Semantic Web Rule Language (SWRL), Rule Interchange Format (RIF) or Common Logic, or in executable SHACL rules, depending on the engine you will run them on
Transactional integrity still belongs in the systems of record. The semantic layer adds cross-system rules; it does not replace the database's own guarantees. We may need to express cross system reversal by compensating transactions at the business process level
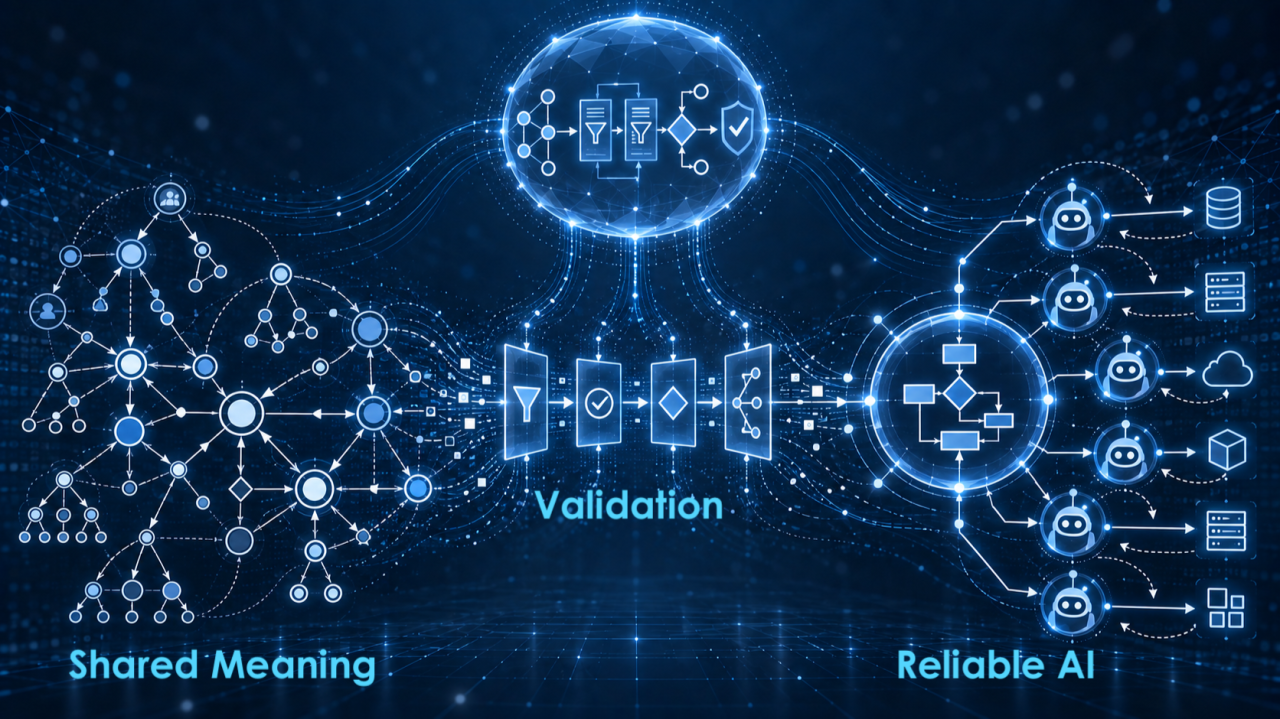
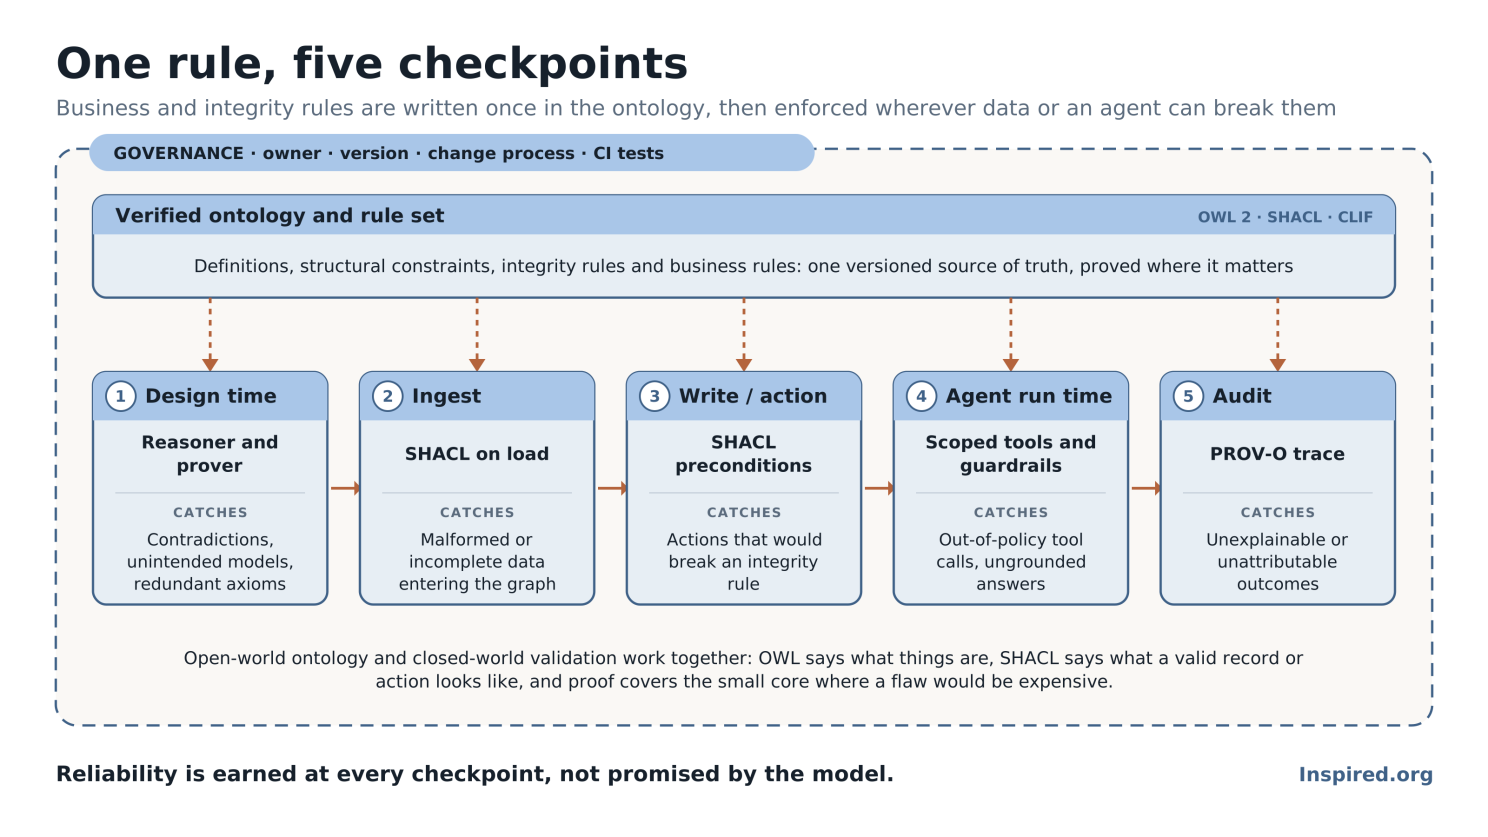
The discipline is to write each rule once, in the ontology and its constraint set, under version control, and then enforce it at every point where it could be broken (figure 2 below). A rule copied into five applications will drift. A rule referenced from one governed source will not.
5. Build the graph
An ontology with no data is a diagram. The production graph is built with the techniques that connect your estate to the model:
Declarative mapping. RDB to RDF Mapping Language (R2RML) and RDF Mapping Language (RML) describe how source tables, files and APIs map to the ontology, so the mapping is itself a governed, reviewable artefact rather than buried pipeline code
Materialise or virtualise. Load the data into the graph, or leave it in place and let ontology-based data access (OBDA) tools such as Ontop answer queries by rewriting them to the source databases. Materialising is faster to query and simpler to reason over; virtualising avoids copies and stays fresh. Most estates end up using both
Identity. A deliberate IRI strategy, and entity resolution (blocking, matching, probabilistic linkage, with tools such as Splink) so that four records for one customer become one. A governed ontology over duplicated entities is still wrong
Pipelines with quality gates. Orchestration (Airflow, NiFi) with SHACL validation as a gate, so bad data is stopped and reported before it reaches the graph
6. Serve and act
Agents and applications need a governed way in. That means a serving layer: SPARQL (with property paths and federation), GQL and Cypher for property graphs, and GraphQL for application developers who want an API rather than a query language. Design it API-first, with caching and access control as part of the design, not afterthoughts.
The more interesting step is the operational semantic layer. Once the ontology describes your entities and how they relate across systems, you can describe actions on them too: approve this order, reassign this case, escalate this claim. An action has a type, parameters, preconditions and effects, all expressed in terms of the ontology. Systems that follow this pattern, Palantir Foundry being the best-known commercial example, can drive workflows across the whole estate without moving the data first.
This is what makes an agent's action safe to permit. The preconditions are the rules from capability 4, so an action that would break an integrity constraint is refused before it commits, whichever agent or person attempted it.
7. Scale and secure
Production brings the questions prototypes avoid.
Scale is largely won or lost through earlier decisions:
The OWL profile you chose in capability 1 sets the ceiling on reasoning cost. Materialising inferences once at load time, rather than reasoning at every query, is a common and effective trade
Modularise the ontology, so that each application loads what it needs, not everything
Index and tune the graph (Cypher query optimisation, the right indexes, avoiding supernodes), use graph algorithms where they add insight, and choose between RDF and property graph per workload, with a bridge between them
Cache the serving layer, and test with realistic volumes before a rollout, not after
Security needs to be designed into the same layers, not bolted on:
Access control at the serving layer. Who may see which graph, entity type or property, and who may invoke which action. Enforce it where the query or action is executed, and keep the policy under version control with the ontology
Least privilege for agents. Expose an agent to a narrow, explicit set of tools, authenticated and authorised in their own right. The Model Context Protocol (MCP) is becoming the common way to offer tools to agents, and its authorisation model builds on OAuth. Treat each tool as an API with a security review
Do not rely on the model to police itself. A prompt that says "never do X" is a request, not a control. Prompt injection means an agent can be talked out of an instruction. The constraint has to sit in the infrastructure, where the agent cannot argue with it
Provenance and audit. Record what was asked, which facts were used, which rules fired and what was done, using a standard such as PROV-O — the PROV Ontology. That is how you answer a regulator, or a customer, who asks why the system did what it did
Platform security (identity management, network, secrets, encryption) is a discipline in its own right and belongs with your enterprise security architects. The semantic layer's job is to make sure the access rules are expressed against meaningful entities and enforced at the point of use.
8. Ground and guard the agents
Now the agent. Grounding means it works over the governed graph rather than raw tables or a pile of text chunks.
Retrieval that follows relationships. Vector RAG finds similar passages. GraphRAG and KAG (knowledge-augmented generation) retrieve over the graph, which suits multi-hop questions, identity-dependent questions and anything that turns on a rule. Evaluate them rather than assume: DeepEval and RAGAS measure whether answers are faithful to the retrieved facts
Context as an engineered asset. A context graph gives the agent memory and a stable picture of the entities it is dealing with, rather than whatever fits in the prompt
A neuro-symbolic loop. The model proposes, the ontology disposes. The agent drafts a plan or an answer, and the symbolic layer checks it against the constraints and the facts before anything happens. A rejected proposal returns to the agent with the reason, so it can try again
Guardrails and an evaluation harness. SHACL and reasoner checks at run time, an automated test suite of realistic scenarios, monitoring in production and a record of every run. This is where "reliable" is earned. It is measured, not asserted
One more thing about speed. An LLM can draft candidate classes and axioms in minutes, and used properly it is a real accelerator. Used carelessly it produces a vibe ontology: plausible, fluent and unverified. The safe pattern is the one from last time, assisted then verified: LLM drafts, then competency questions, OntoClean, reasoner and SHACL as gates, with a human reviewing and the provenance recorded.
Governing it as software
An ontology that drives production systems is a production artefact. It needs the lifecycle you would give any critical software: an owner, versioning, a change process, automated tests on every change, a release process, and a way to deprecate rather than delete. Methodologies such as NeOn give you a full ontology-engineering lifecycle. The practical rule is simple: nothing reaches production that has not passed the tests.
A minimum viable production kit
As before, you do not need all of it at once. For one domain and one agentic use case, a defensible first production release is:
A verified ontology core with its competency-question test suite, and a reasoner consistency report
A SHACL constraint set covering the structural, integrity and business rules for that use case
A source-to-graph mapping and a populated graph with entity resolution and quality gates
A governed serving layer with access control, and one typed action with its preconditions
One grounded agent with run-time guardrails, an evaluation harness and an audit trace
A governance pack: owners, versions, change process and release gates
That is a small system, but it is complete: it can be run, tested, secured, audited and extended. The next domain reuses most of it.
The skills, in one place
Last time the role was the semantic translator. The role here is the person who turns that translation into infrastructure, an ontology and knowledge engineer for agentic systems:
Formal modelling: OWL 2 with deliberate profile choice, design patterns, and ontological analysis with OntoClean and upper ontologies
Verification: competency-question testing, DL reasoning, and first-order proof and model finding for the critical core
Constraint engineering: SHACL and rule languages, and the judgement to put each rule in the right place
Data engineering for graphs: declarative mapping, OBDA, identity and entity resolution, pipelines with quality gates
Serving and action design: SPARQL, GQL, GraphQL, access control and action modelling
AI engineering: GraphRAG and KAG, context engineering, agent guardrails, evaluation and monitoring
Governance: ontology lifecycle, versioning, provenance and audit
It is a demanding profile, but it is learnable. Most of the people who can learn it are already in your organisation, working as modellers, data engineers and architects.
How we're approaching it
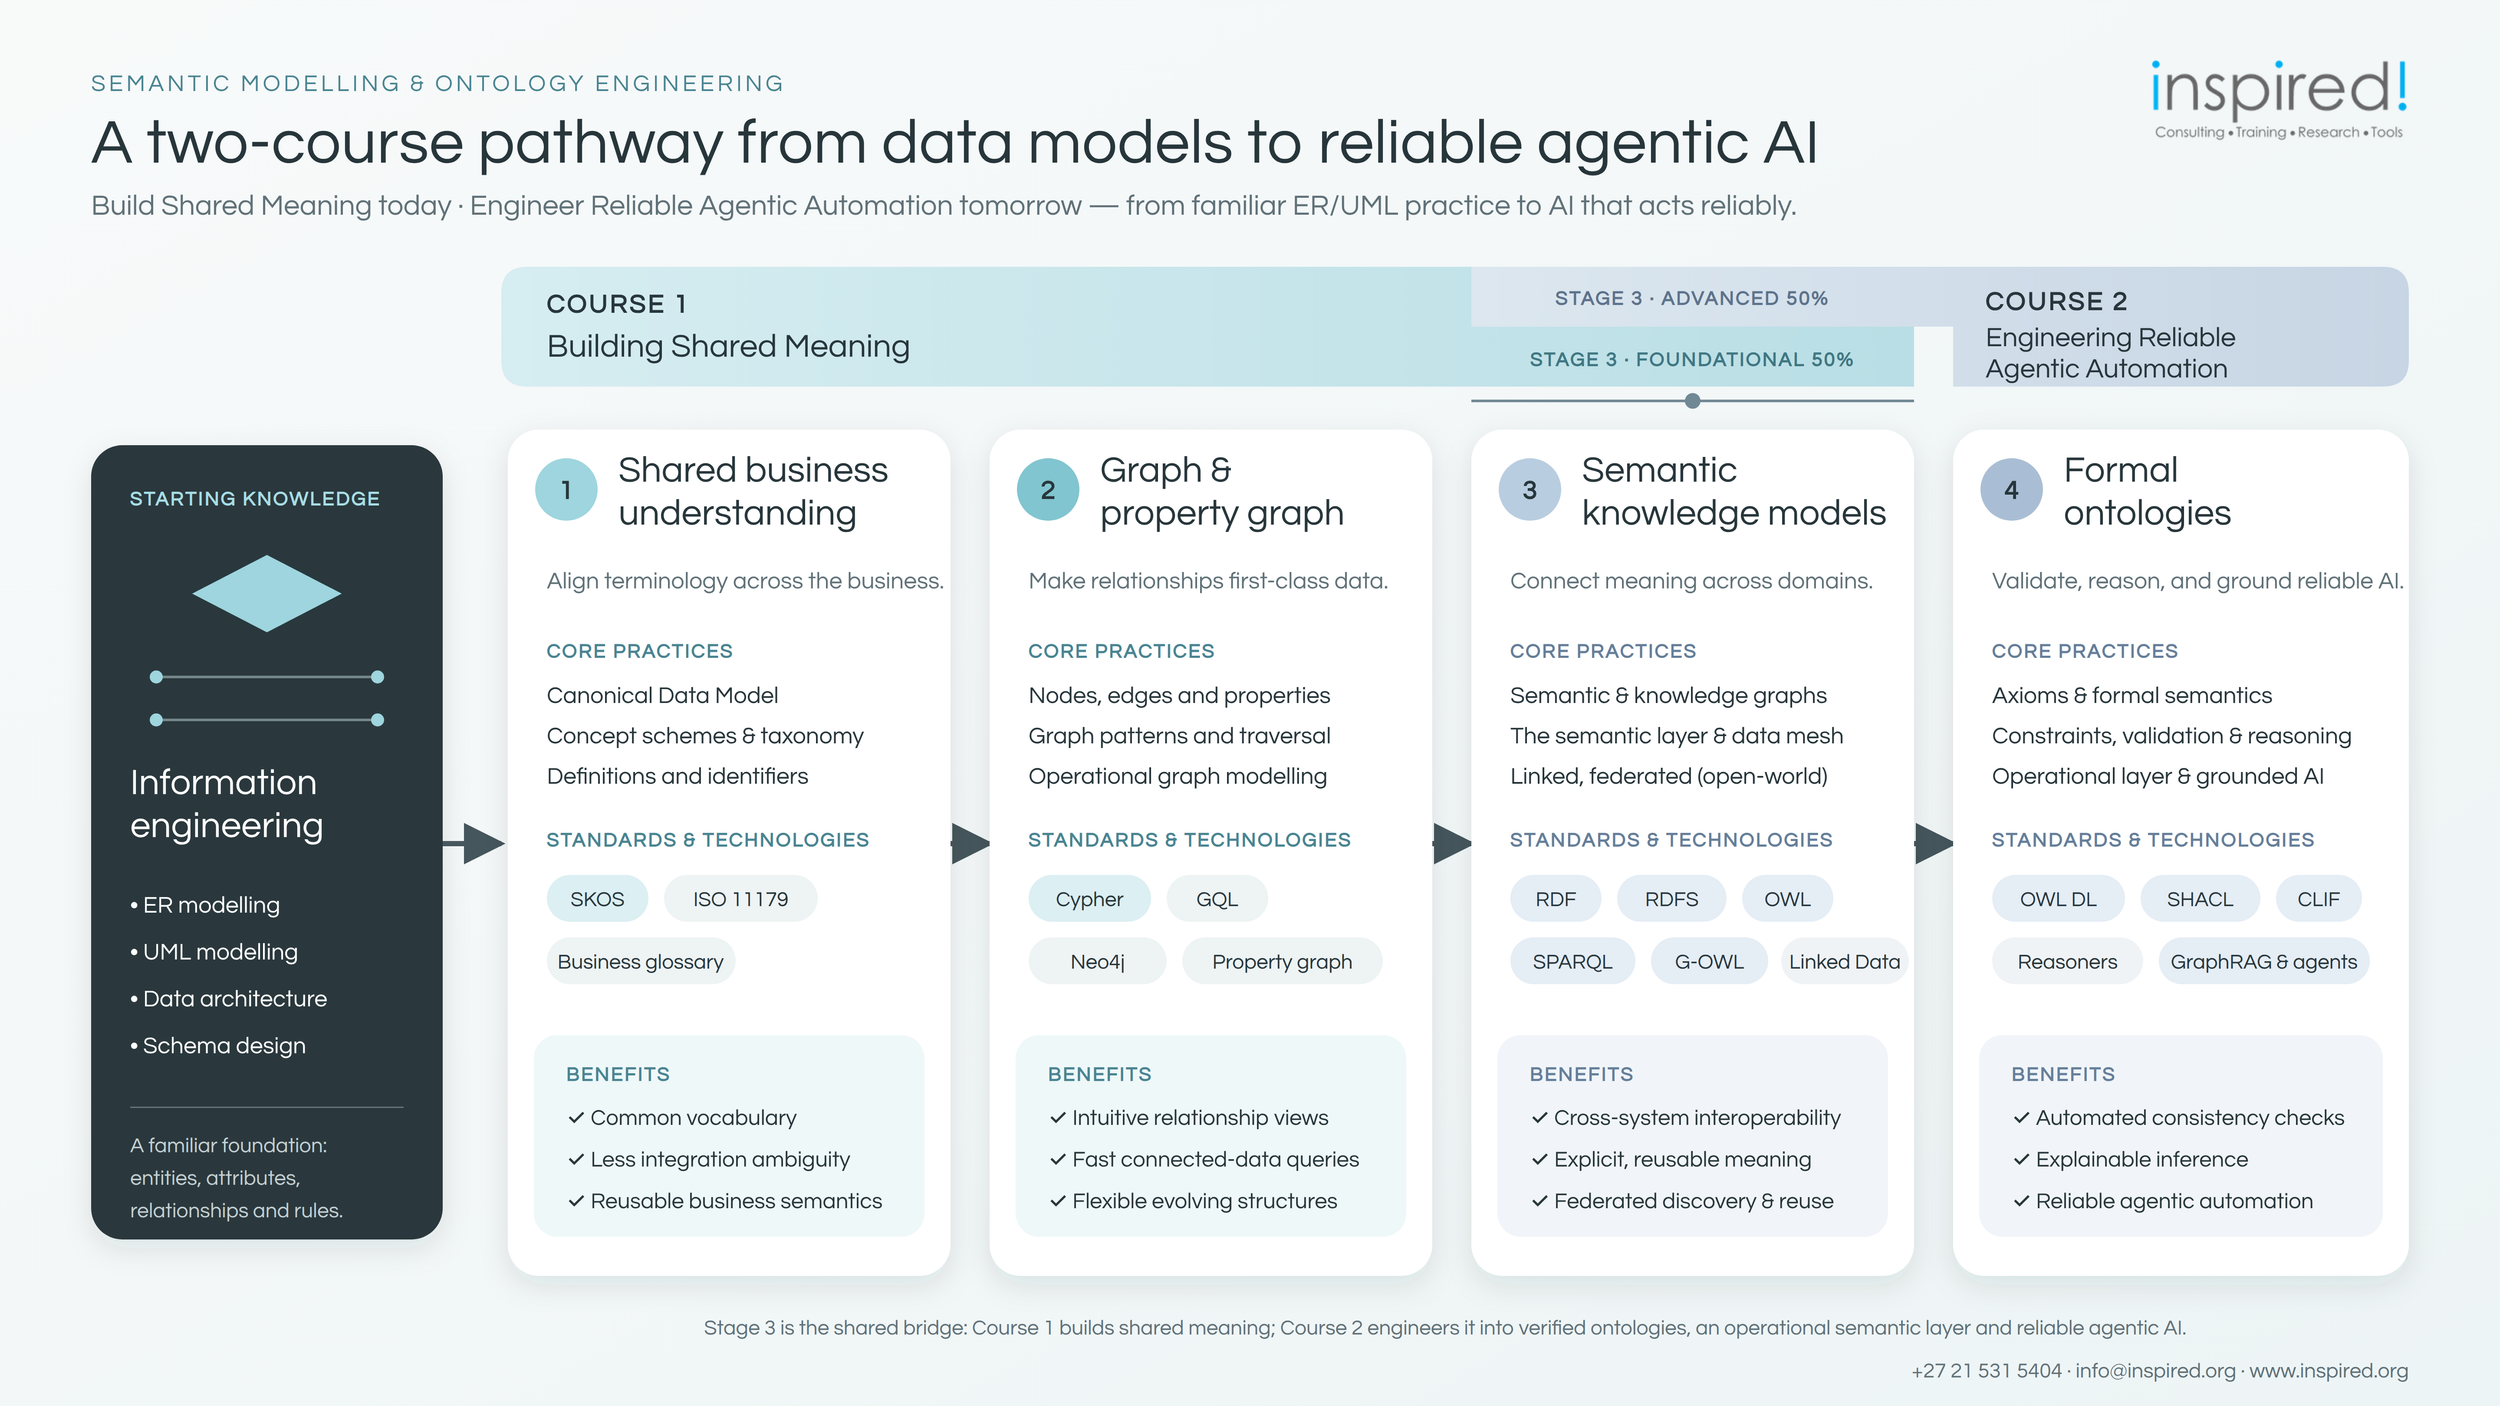
This is the ground the second course of our pathway covers, under the same line as the first: Build Shared Meaning Today to Engineer Reliable Agentic Automation Tomorrow.
Course 2 — Engineering Reliable Agentic Automation is for modellers and ontologists, data, ML and AI engineers, and solution architects. It builds on Course 1 (or equivalent: RDF and OWL basics, SPARQL and property graphs) and expects some programming familiarity, for example in Python. Over four and a half days it works through capabilities 1 to 8 at working-to-deep level:
rigorous modelling: OWL 2 in depth, design patterns, OntoClean and upper-ontology alignment
constraints, validation and formal reasoning: SHACL, DL reasoners, Common Logic and CLIF, and verification with a theorem prover and a model finder
engineering the knowledge graph: mappings and OBDA, entity resolution and pipelines, graph performance and algorithms, and the serving layer in SPARQL, GQL and GraphQL
the operational semantic layer and agentic AI: virtual knowledge graphs, the action layer, GraphRAG and KAG, and grounding agents with context engineering
reliability, safe acceleration and a capstone: guardrails, evaluation and governance, LLM-assisted construction done safely, and an end-to-end system presented to peers
Every skill is taught on open standards, with the mainstream tools named for each topic. Access control and auditability are built into the serving, agent and reliability sessions. Wider platform security remains the job of your security architecture, and we say so. Participants leave with a working system for a domain of their own: a verified ontology, its constraint suite, a populated graph, a serving layer and a grounded agent with its guardrails and evaluation harness. More on both courses in the posts that follow.
Details of our two course path →
If you would like to discuss the implications of the above for your specific organisation or situation, please book a slot with me:
References and standards
W3C, OWL 2 Web Ontology Language Primer, 2nd edition, 2012 — https://www.w3.org/TR/owl2-primer/ · OWL 2 Profiles, 2nd edition, 2012 — https://www.w3.org/TR/owl2-profiles/
Guarino, N. & Welty, C. (2009), "An Overview of OntoClean", in Handbook on Ontologies, 2nd edition, Springer.
ISO/IEC 21838-2:2021, Top-level ontologies — Basic Formal Ontology (BFO). Arp, R., Smith, B. & Spear, A. (2015), Building Ontologies with Basic Formal Ontology, MIT Press.
Presutti, V. et al. (2009), "eXtreme Design with Content Ontology Design Patterns"; Gangemi, A. & Presutti, V. (2009), "Ontology Design Patterns", in Handbook on Ontologies.
Glimm, B. et al. (2014), "HermiT: An OWL 2 Reasoner", Journal of Automated Reasoning; Kazakov, Krötzsch & Simančík (2014), "The Incredible ELK", Journal of Automated Reasoning.
Poveda-Villalón, M., Gómez-Pérez, A. & Suárez-Figueroa, M. C. (2014), "OOPS! (OntOlogy Pitfall Scanner!)", International Journal on Semantic Web and Information Systems.
ISO/IEC 24707:2018, Information technology — Common Logic (CL). Grüninger, M. et al., COLORE: Common Logic Ontology Repository.
W3C, Shapes Constraint Language (SHACL), Recommendation, 2017 — https://www.w3.org/TR/shacl/ (SHACL 1.2 in Working Draft). Labra Gayo, J. E. et al. (2018), Validating RDF Data, Morgan & Claypool.
W3C, R2RML: RDB to RDF Mapping Language, Recommendation, 2012 — https://www.w3.org/TR/r2rml/. Dimou, A. et al. (2014), "RML: A Generic Language for Integrated RDF Mappings of Heterogeneous Data".
Xiao, G. et al. (2018), "Ontology-Based Data Access: A Survey", IJCAI. Calvanese, D. et al. (2017), "Ontop: Answering SPARQL queries over relational databases", Semantic Web.
W3C, SPARQL 1.1 Query Language and Federated Query, Recommendations, 2013 — https://www.w3.org/TR/sparql11-query/. ISO/IEC 39075:2024, GQL.
W3C, PROV-O: The PROV Ontology, Recommendation, 2013 — https://www.w3.org/TR/prov-o/
Model Context Protocol — https://modelcontextprotocol.io/ (check the current specification and its authorisation section).
Edge, D. et al. (2024), "From Local to Global: A Graph RAG Approach to Query-Focused Summarization" — arXiv:2404.16130. Liang, L. et al. (2024), "KAG: Boosting LLMs in Professional Domains via Knowledge Augmented Generation" — arXiv:2409.13731.
Pan, S. et al. (2024), "Unifying Large Language Models and Knowledge Graphs: A Roadmap", IEEE TKDE.
Suárez-Figueroa, M. C., Gómez-Pérez, A. & Fernández-López, M. (2012), "The NeOn Methodology for Ontology Engineering", in Ontology Engineering in a Networked World, Springer. Kendall, E. & McGuinness, D. (2019), Ontology Engineering, Morgan & Claypool.
Grüninger, M. & Fox, M. (1995), "Methodology for the Design and Evaluation of Ontologies", IJCAI Workshop on Basic Ontological Issues in Knowledge Sharing.